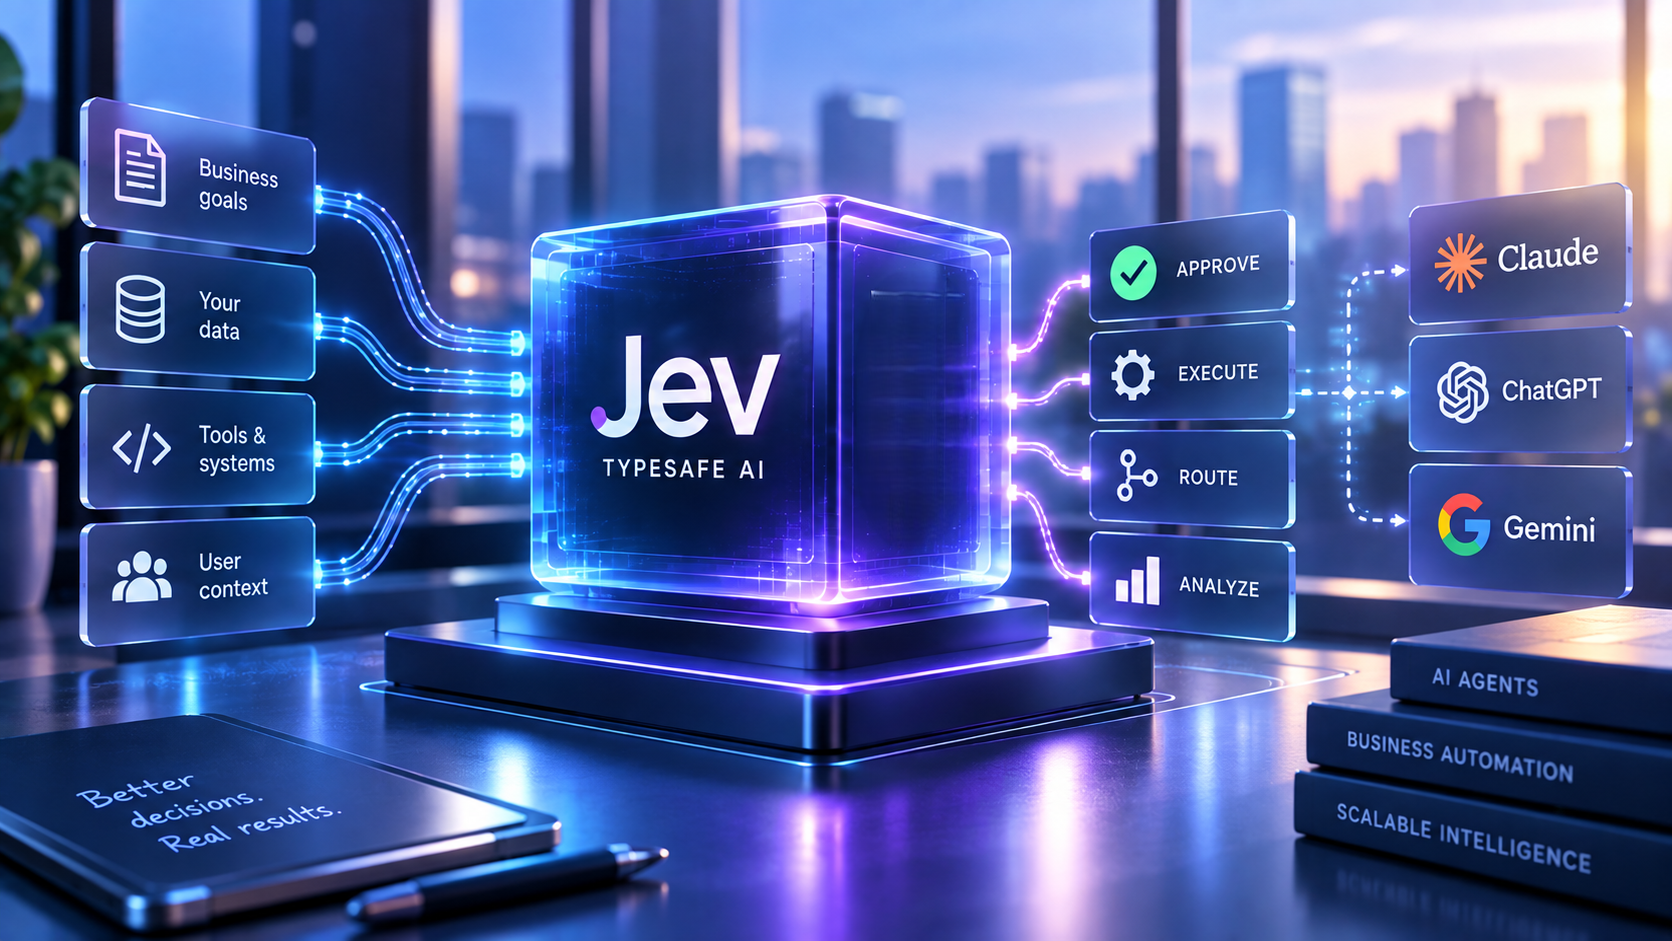
Most AI tools want to talk. They write the email, explain the reasoning, offer three options and a polite sign-off. That is useful when you need writing. It is expensive and sloppy when you only needed a decision.
Jev, from a startup called TypeSafe AI, does the opposite. It will not draft a reply. It will not write code. It will not build a slide deck. You give it messy input, like a customer email, and a fixed list of answers: billing, technical, sales or spam. It returns a label, a score and a probability. That is the whole product.
Think of a junior assistant whose only job is to put mail into trays. They do not write back. They do not invent a new tray. They tell you how sure they are. Software can work with that. Software cannot work with a two-paragraph maybe.
The founder, Diogo Almeida, helped invent the training method behind ChatGPT at OpenAI, then left to build models that only make this kind of call. TypeSafe calls them System One models. Jev is the first public one. Early access opened in mid-September. Most people still wait for a key.
Why the price is the story
Input costs $0.042 per million tokens, or $42 per billion. Output tokens are free. Answers come back in 70 to 500 milliseconds. TypeSafe’s own tests claim huge speed and cost gaps versus a big chatbot. Treat those numbers as marketing until you run your own pile.
Outside tests are more useful. An engineer at Vercel found Jev five to eighteen times faster than an OpenAI model when checking whether a command was safe. A company called Bryo compared it with Gemini for sorting business email. Gemini was a bit more accurate. It was also ten to twenty times more expensive. Bryo kept Jev because it hands back a real probability. That number is what you need before software is allowed to act.
A 0.94 on “billing” can auto-tag the ticket. A 0.51 should go to a human. Chatbots often sound certain either way. Jev is built to say when it is guessing.
You do not open a chat tab to use it. You put it behind the tools you already run, such as n8n, Make or a short script. One web request goes in. A structured answer comes out.
Why a non-technical owner should care
Look at your last hundred incoming messages. How many needed a written reply on arrival? How many only needed someone to say: this is billing, this is spam, this is urgent, this is a real lead?
You are probably paying ChatGPT or Claude to do both jobs. First they decide the tray. Then they write the letter. The first job does not need an essay. It needs a bucket and a confidence score.
Put Jev in front of the model you already pay for. Let the expensive model work only on the leftovers.
Ignore Jev if you sort a few dozen items a day. The saving shows up when the queue is daily and counted in hundreds: support mail, form fills, reviews, inbound leads.
What an SMB should test this week
- Support and sales inbox. Give Jev four trays: billing, technical, sales, spam. Ask for an urgency score from 0 to 100. Rule of thumb: if it is less than 80 percent sure, or urgency is over 80, send it to a person or to Claude. Everything else can auto-tag in HubSpot or Gmail. After 200 messages, count two things. Did you miss urgent tickets? How much chatbot usage did you stop buying?
- Lead quality gate. Before your sequencer sends a custom email, ask three yes/no questions. Is this a real company? Is the ask in scope? Is there any budget signal? Low confidence stays in the CRM. High confidence gets the sequence. This is where small companies burn money: beautiful emails written to junk leads.
- Reviews and contact forms. Score each one as praise, complaint or possible legal risk. Auto-publish only very confident praise. Park the rest.
- A safety check on drafts. After ChatGPT or Claude writes a client reply, send the draft plus your policy to Jev: “safe to send?” If the probability is not high, do not send. That is the highest-leverage test for any agency already generating client-facing text.
Do not fire your writer. Replace the “read this and decide which bucket” step that currently costs real money and still invents a reason.
What a solo should test this week
- Join the waitlist and run 100 real items. Not demo text. The last 100 support emails or form fills you actually received. If Jev plus an 80 percent cutoff matches your own sorting about 90 percent of the time, keep it. If it is around 70 percent, either your trays are wrong or this job still needs a full chatbot.
- Price the loop. What do you spend today to classify that pile? At Jev’s input price the same pile is usually cents. If you cannot feel the saving, your volume is too low. Wait until the queue is daily.
- Wire it once in the automation tool you already use. If you only live in ChatGPT, Jev will feel like a brick. That is a setup problem, not a reason to force it into chat.
Skip Jev if a client, a regulator or a junior needs to know why. It will not explain itself. That is the trade.
The honest limits
Waitlist. No writing. No code. No “because.” Accuracy can sit a few points under a big model. You can only offer so many labels at once. The price looks subsidised, so do not build a whole product on $42 per billion lasting forever. Early access had a few serving hiccups.
Recommendation: test, not adopt. After 200 live items, did you cut model spend without increasing bad auto-actions? If yes, keep it as the first pass. If you still need a paragraph of reasoning before you trust the route, stay on Claude and pay the tax.